stackmini
a self-hosted AI appliance. one guided CLI, hailports setup, picks the right build and model for your machine and gets you to a working chat. macOS (apple silicon and intel), windows 10/11, linux.
see it work
three ways to run it
fully local. llama.cpp, with the build and model chosen for your GPU and RAM. the reference setup uses MiniCPM-V on a base M4 mac mini with 24GB. see dated measurements on the live board.
hybrid. local first. it escalates to a cloud model only for the hard parts and shows you the tokens it saved.
pure API. OpenAI-compatible, Anthropic or Google. keys live only in your env or keychain.
what is in the box
- terminal and browser chat, with image input
- web search and fetch
- a notes brain with embeddings
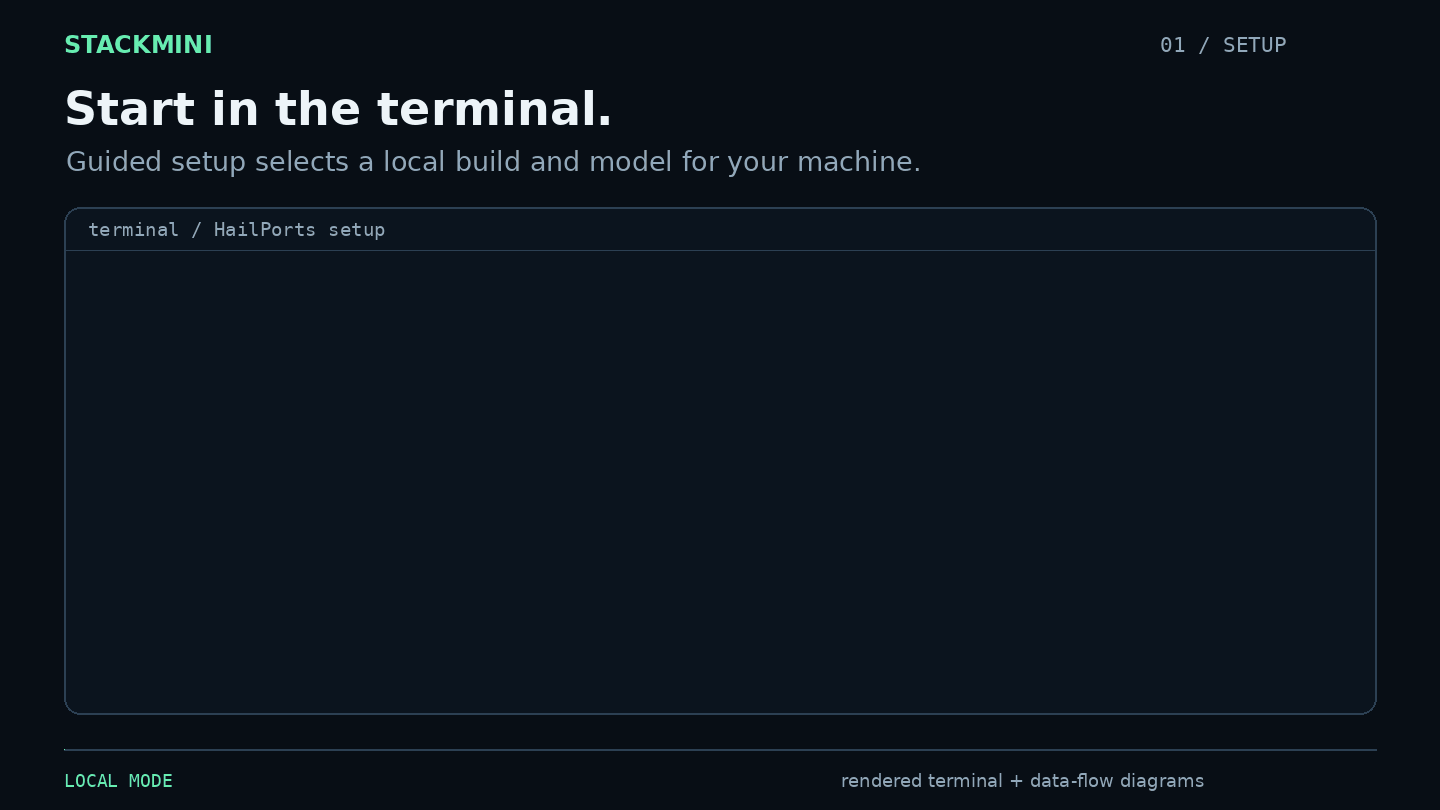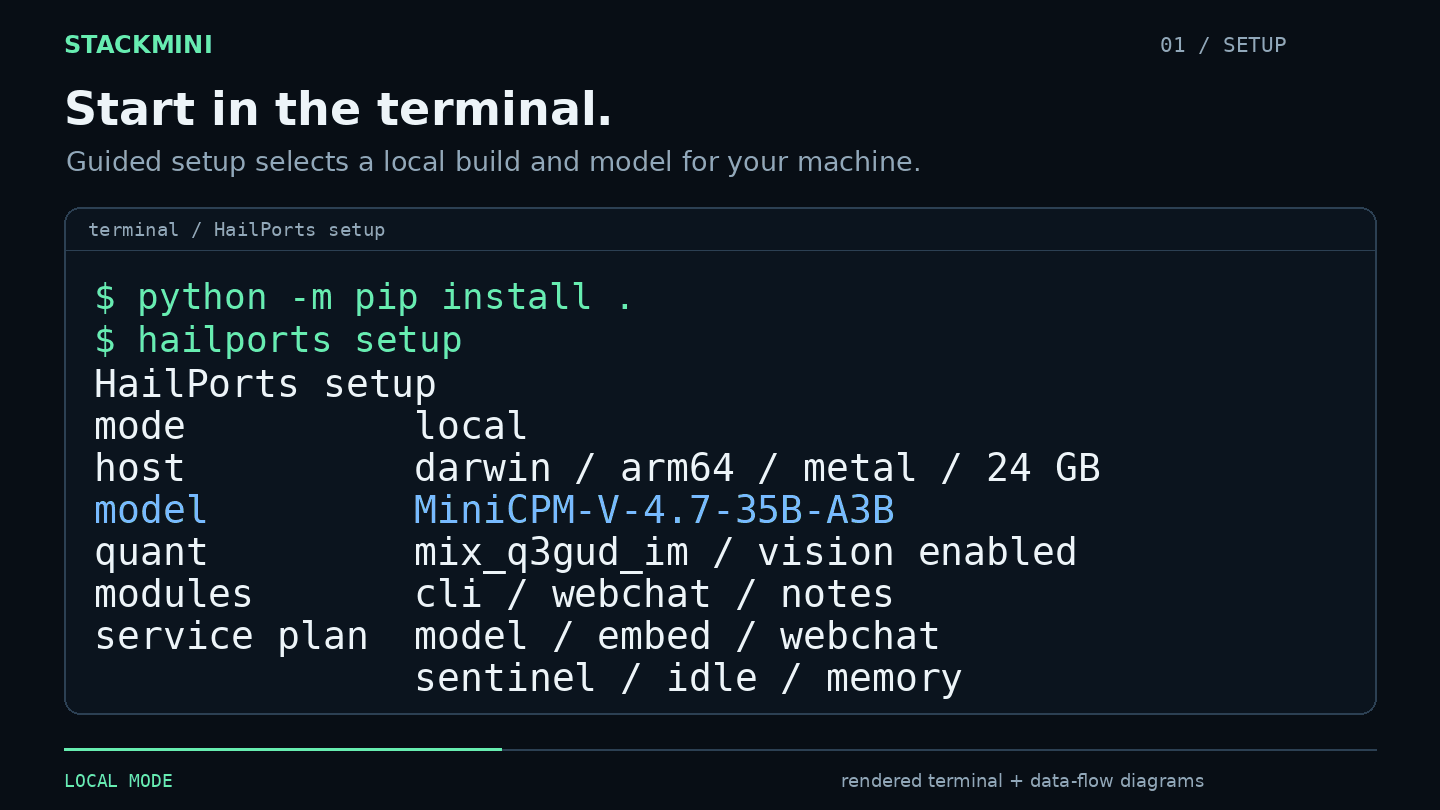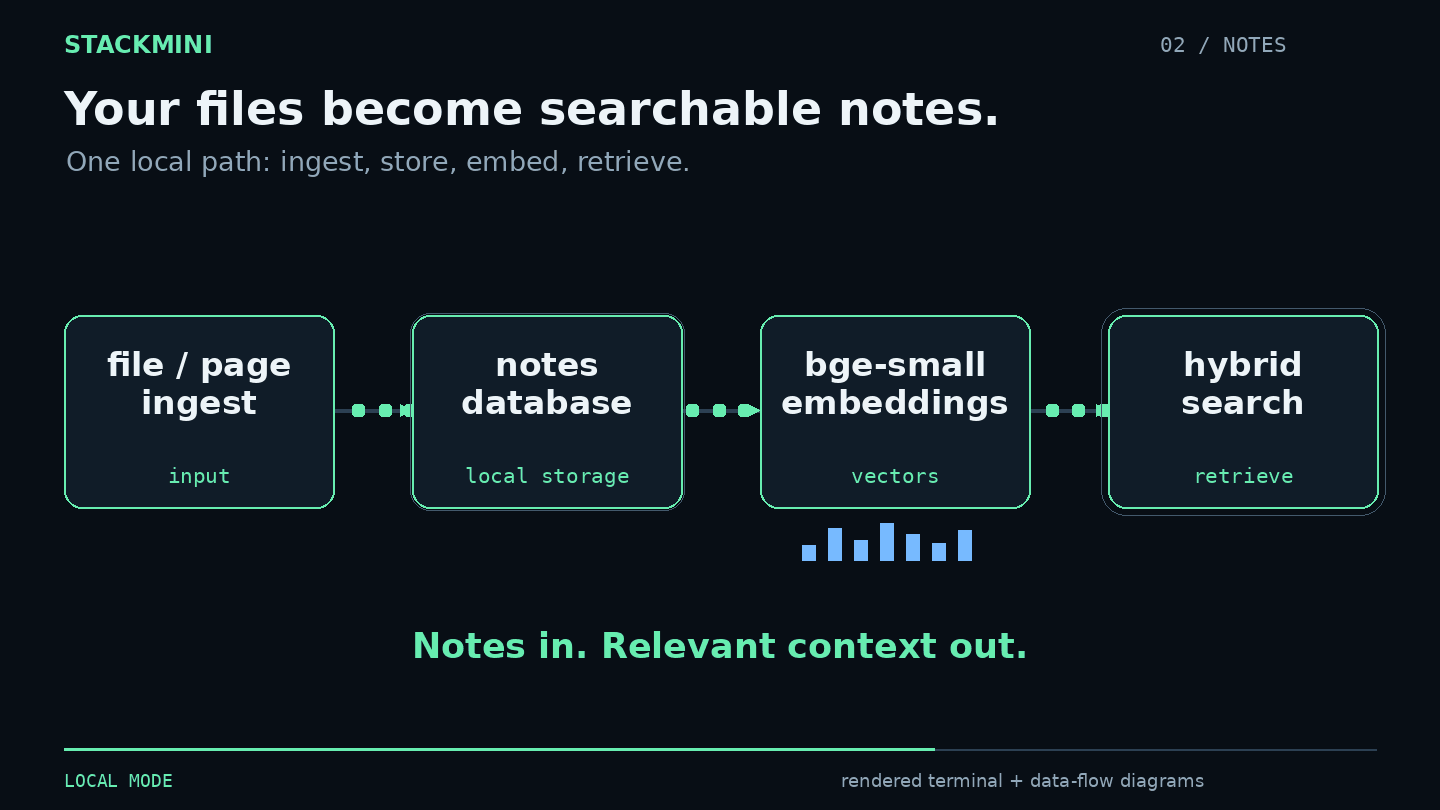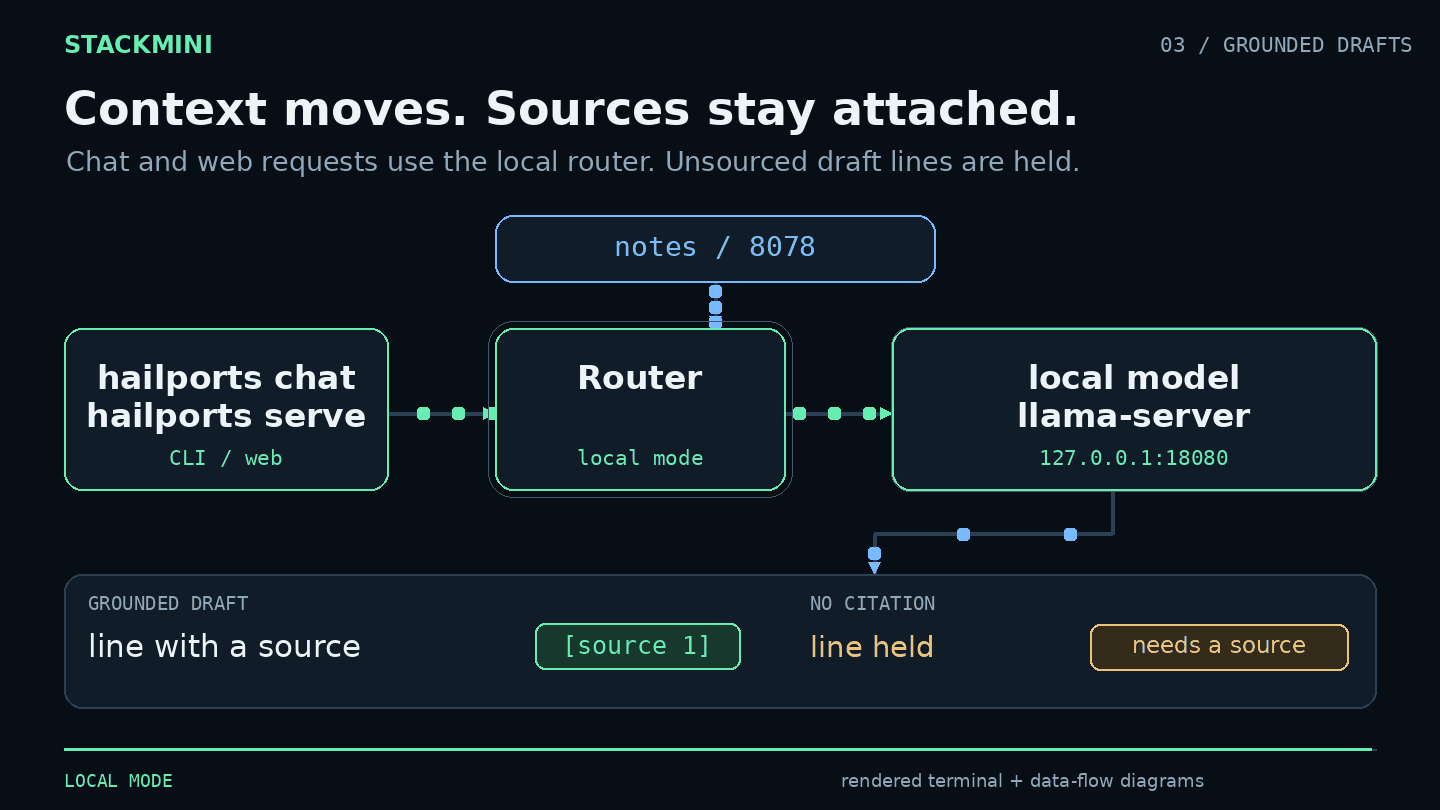
- a grounded drafter that cites your own notes
- runbooks, plus a learning loop that picks up your corrections
- an idle-work scheduler and a self-healing watchdog
- an iMessage bridge on mac
hailports doctorto check the install
it listens on localhost by default and sends no telemetry.
stackmini setup checklist
every install step, mode, model size, port and server flag from the repo docs on one printable page. drop your email and the link shows up right here.
get the build log
new setups, numbers and guides when they ship. no spam, unsubscribe any time.